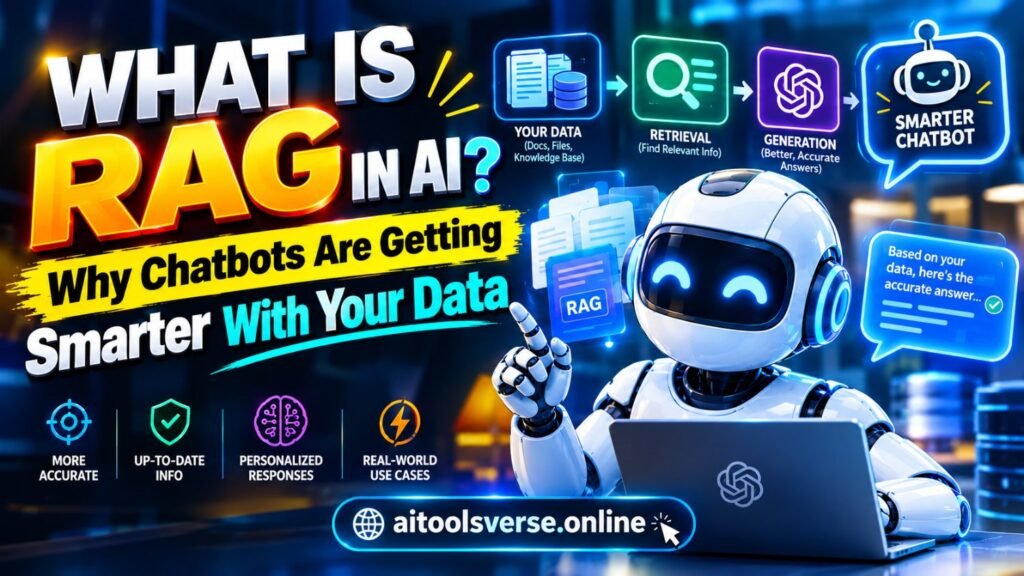
Ask a normal chatbot about your company’s refund policy and it will guess, politely and confidently, because it was trained months ago and has never seen your policy. Ask a RAG chatbot the same question and it looks the policy up first, then answers from what it found. That difference is the whole idea. So what is RAG in AI? RAG stands for retrieval-augmented generation, and it means: retrieve the relevant facts first, then generate the answer from them.
The name sounds technical, but the habit is familiar. It is the difference between answering an exam from memory and answering with the textbook open. A normal chatbot works from memory — its training. A RAG system works open-book: it searches a collection of documents, pulls out the most relevant passages, hands them to the language model, and says, in effect, “answer using this.” The answer is usually more accurate, more current, and easier to check, because you can see which passages it used.
Why chatbots needed RAG
Language models have three well-known weaknesses. Their knowledge freezes on the day training ended, so they know nothing about last week’s events. They invent facts when they are unsure, because fluent guessing is what they were trained to do. And they know nothing about your private documents — your manuals, your price lists, your course notes — unless someone gives them access. RAG tackles all three at once, without retraining the model. You just change what it is allowed to look up.
This is also much cheaper than the alternative. Retraining a large model on new data costs a fortune and takes weeks. Updating a RAG document collection takes minutes: add the new manual, remove the old price list, and the next answer reflects the change. For businesses, that alone makes RAG the practical choice for most question-answering tools.
How RAG works, in seven steps
First, your documents are collected: PDFs, web pages, help articles, spreadsheets. Second, they are split into small chunks, usually a few paragraphs each, because a whole manual is too big to hand to a model at once. Third, each chunk is turned into a numerical representation, called an embedding, which captures its meaning in a form a computer can compare. Fourth, those embeddings are stored in a searchable index, sometimes called a vector database.
Fifth, when you ask a question, your question is turned into an embedding too, and the system finds the chunks whose meaning is closest to it. Sixth, the best chunks are pasted into the model’s prompt alongside your question. Seventh, the model writes its answer based on those chunks, ideally citing them.
If any step is weak, the answer suffers. Bad chunking means the key sentence is split across two chunks and neither looks relevant. A messy document collection means the search returns outdated pages. A model that ignores the retrieved text and answers from memory anyway defeats the whole purpose — and yes, that happens, which is why good RAG tools show their sources.

Where you have already met RAG
If you have used a search chatbot that answers with citations, you have used RAG. Perplexity is the best-known example: it searches the web, retrieves pages, and answers from them, with links you can open. Our Perplexity AI guide walks through how that feels in practice. Customer support bots that answer from a company’s help centre are RAG too. So are study tools that answer from your uploaded lecture notes, and legal or medical assistants that answer from a curated library instead of from general training.
Students get particular value here. Upload your course notes to a RAG study tool and you can ask, “What did the lecturer say about photosynthesis?” and get an answer grounded in your actual notes, not a generic textbook summary. Just remember the privacy rule: do not upload anything sensitive to a tool you do not trust. For the underlying concepts, read what is a large language model first, and keep Notion AI in mind as a notes tool that pairs naturally with this approach.
RAG is not magic either
Honest limits matter. RAG only helps if the right documents exist and the search finds them. If your collection is incomplete, the system will answer from whatever it found, which may be the wrong document. If the retrieved passages contradict each other — an old price and a new price — the model may pick the wrong one or blend them. And RAG does not fix a model that hallucinates: it reduces hallucinations, it does not eliminate them. The sources shown are your safety net. Open them, especially when money, health or grades are involved.
There is also a quality question in how the system ranks chunks. A short, keyword-matching chunk can outrank a longer, more accurate one. Good RAG products tune this carefully and let you see or adjust the sources. When evaluating a tool, ask one question: can I see exactly which passages it used? If the answer is no, treat its answers with the same caution as any chatbot.
Should you build or buy a RAG tool?
For most people, buying is the right answer: use a product that already does RAG well, like a search chatbot or a support platform with document search built in. Building your own makes sense only if you have a large private collection and a team to maintain it — the chunking, the index, the updates, the access controls. Either way, the discipline is the same: keep the collection clean, current and permissioned, because the chatbot is only as trustworthy as the shelf it reads from.
For further reading, IBM’s RAG explainers and Pinecone’s RAG guide describe the pattern in more depth, with diagrams that make the seven steps above click visually.
Frequently asked questions
What is RAG in AI? Quick answers
Is RAG the same as fine-tuning? No. Fine-tuning retrains the model itself; RAG leaves the model unchanged and gives it better material to read at answer time. RAG is faster, cheaper and easier to update.
Does RAG make chatbots always accurate? No, but it makes them noticeably more accurate and checkable, because answers can be traced to sources you can open.
Can RAG work with my own documents? Yes, that is its most popular use. Upload manuals, notes or policies to a RAG tool and ask questions about them — while respecting privacy and copyright.
RAG is a simple idea with an outsized effect: let the model read before it speaks. It will not make chatbots perfect, but it makes them current, grounded and checkable — and for most real work, that is the difference between a toy and a tool.
For the other side of this problem, see our guide on AI hallucinations: why AI makes things up and how to check facts.